Sarvam Prism: 44-Millisecond AI Decisions, Run on Your Own Servers

Amir Farid
7 min read
Sarvam AI launched Prism on 4 November 2026. It is a decision-making model, built as a LoRA fine-tune of Sarvam's 105B base model. Unlike a chatbot, Prism does not generate text token by token. It processes an input in a single forward pass and returns a probability score for each available option. Sarvam says it responds in 44 milliseconds on an NVIDIA B200 GPU. For businesses, that matters because most operational AI work is routing, classifying, scoring and triaging thousands of small decisions, not writing essays.
Prism's weights are released under the Apache 2.0 licence on Hugging Face, according to the Hindu BusinessLine report on the launch, so enterprises can fine-tune it on their own data and run it on their own infrastructure. It is also available through Sarvam's API. This post explains what Prism does, where it beats a general model, and how to pilot it safely.
Sarvam Prism: 44-Millisecond AI Decisions, Run on Your Own Servers
What Sarvam Prism actually does
Sarvam describes Prism as a System 1, Jev-like decision model: fast, pattern-based judgement. Is this ticket urgent? Does this document belong in this category? Should this request pass this check? You give Prism a set of options, and it scores each one in one pass, rather than drafting a reasoned answer.
That is why a general model is wasteful for constrained answers. If a ticket can only go to billing, technical support or refunds, you do not need a paragraph. You need a reliable score for each route, delivered instantly, so the ticket moves. Prism will not write replies or negotiate contracts. It makes the small decision in front of those tasks, so a slower model is used only where reasoning adds value.
Why 44 milliseconds changes the automation maths
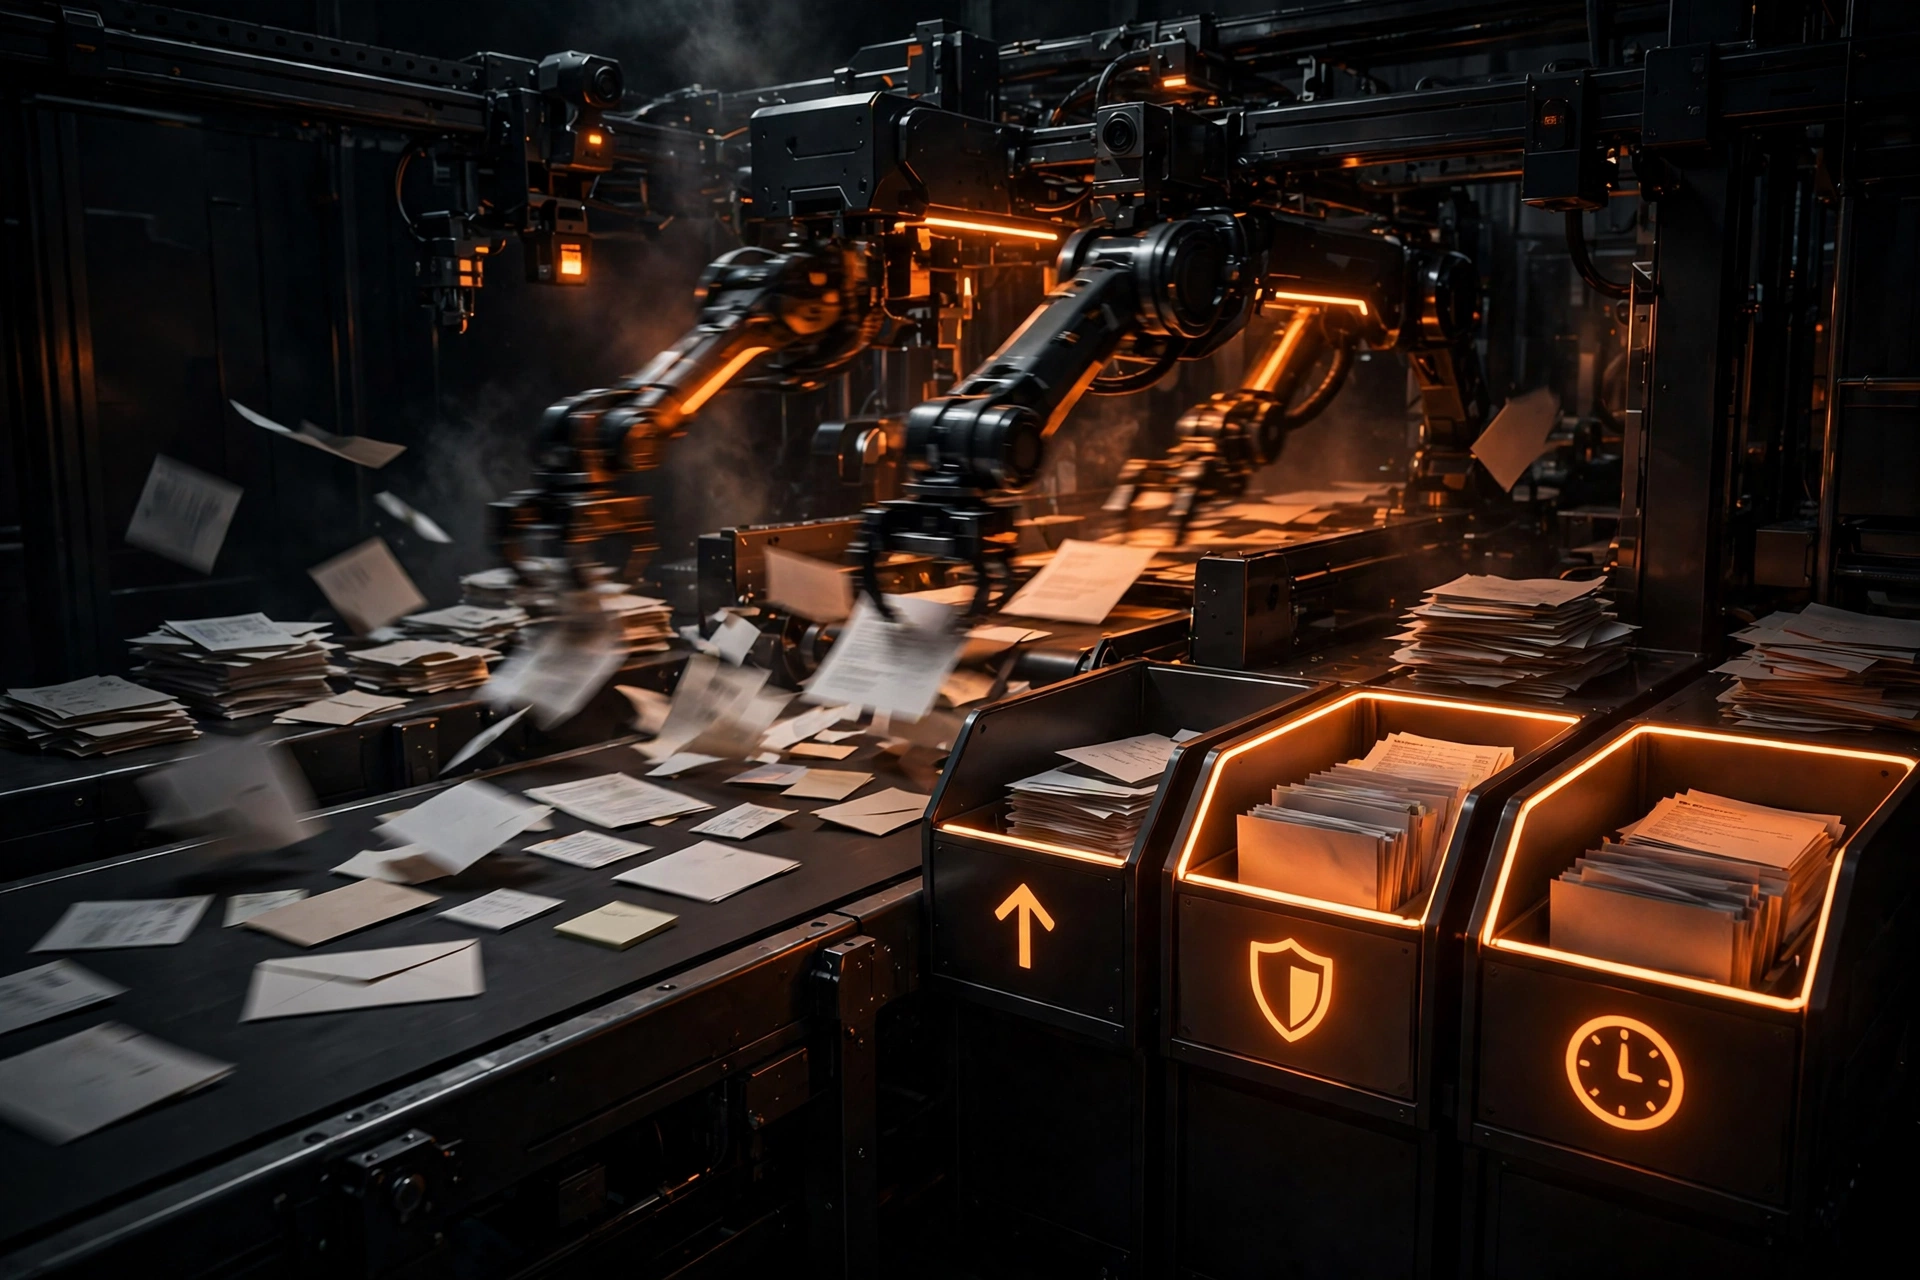
Speed decides where automation can live. A model taking several seconds cannot sit inside a live support queue, a document upload flow or a real-time security check without making the user wait. A model answering in 44 milliseconds, as Sarvam claims for Prism on an NVIDIA B200 GPU, can sit inline: every ticket scored before it reaches an agent, every document triaged on upload.
Sarvam reports an average score of 71.8 across three benchmarks — the Jev Decision Index, Sarvam's recreation of the Artificial Analysis Decision Index, and an internal Indian-language benchmark — and claims Prism outperformed 25 other decision models tested that responded in under 100 milliseconds. Those are Sarvam's claims, not independently verified results. Test Prism on your own past decisions instead. As a rough estimate only, removing seconds of decision delay stops the decision blocking the job, which matters most at high volume.
Decision model vs general LLM: when to use each
Choosing between them is not about which is smarter. It is about what the task needs. This split matters for teams building AI agents or AI automation.
- Decision model, such as Prism: known options, high volume, instant response, auditable results. Examples: routing, classification, scoring and triage.
- General LLM: open-ended tasks needing natural language, multi-step reasoning or explanation. Examples: drafting replies and summarising complex cases.
- Both together: the strongest pattern. The decision model triages; the general model handles cases needing language or judgement. A chatbot or WhatsApp bot can use the same split.
This also helps cost control, though no price is stated here for Prism or Sarvam's API. You avoid spending time and compute on a large model answering a question with only four possible answers. See also our guide to AI agents for small business automation and AI chatbots versus AI agents.
Where Prism fits in real business workflows
Sarvam positions Prism for fast, structured decisions: customer support routing, document analysis and intelligence, security checks, and evaluation of AI-agent performance. Each maps onto work businesses already do by hand, or with slow, brittle rules.
Support routing and document triage
Support queues fail when tickets sit unassigned or bounce between teams. Prism scores intent, urgency and likely team on arrival, so routing stops depending on keywords. Low-confidence cases still go to a human, with a suggested route and score. Accurate classification also improves later answers, as explained in our guide to retrieval-based chatbots for business.
Document work follows the same logic. Invoices, applications and claims arrive faster than teams can read them. Prism-style scoring can classify a document, flag missing fields and route it to the right reviewer before anyone opens it. It decides what needs review first, which is often the bottleneck, including in operations covered by our guide to AI automation for logistics companies.
Security checks and agent quality checks
Security checks and agent evaluations must be fast, consistent and logged. A decision model can score whether a request looks risky or an agent's action matches policy, before the action reaches a customer. That makes it a guardrail inside an agent system, not just a weekly audit report.
Open weights, your servers, your data
Prism's Apache 2.0 licence means enterprises can fine-tune it on their own data and run it on their own infrastructure. That matters for regulated work: you are not forced to send every decision to an outside API, and you can adapt the model to your own labels rather than accepting a generic classifier.
There is a hardware condition to plan for. Per Sarvam's announcement coverage, Prism runs in FP8 precision on a single GPU with at least 120 GB of memory. Start through the API, prove decision quality on real cases, and move to self-hosting only when volume or data control justifies the hardware. Our custom software development team builds this staged rollout, as discussed in our posts on Mistral Large 4 and open weights for business and governed AI agents with NVIDIA NeMoClaw.
A practical pilot plan: prove value in two weeks
Do not start by replacing your workflow. Start with one decision, one dataset and one success metric. A two-week pilot, as a rough planning estimate only, is enough to learn whether Prism earns its place.
- Pick one closed decision. Fixed outcomes only, such as routing tickets to five teams.
- Build a labelled test set. Take 500 to 1,000 past cases with correct outcomes recorded, holding back a portion for testing.
- Score, do not deploy. Run Prism in shadow mode: it scores live cases, but your existing process still decides.
- Set a confidence rule. Auto-route only high-confidence scores; send the rest to a human with the score attached.
- Decide on evidence. Go live only if accuracy, speed and auditability beat your baseline on the held-out set.
This approach works across markets, whether you serve customers in the United Kingdom, the UAE, Saudi Arabia, Pakistan or the USA. It also applies to restaurant groups using our restaurant ERP. If you want help designing that pilot, talk to Coheser.
Frequently asked questions
What is Sarvam Prism?
Prism is a decision-making model from Indian AI company Sarvam AI, launched on 4 November 2026. Built as a LoRA fine-tune of the Sarvam 105B base model, it processes an input in a single forward pass and returns a probability score for each available option, rather than generating text token by token.
How fast is Sarvam Prism, and is the speed verified?
Sarvam says Prism responds in 44 milliseconds on an NVIDIA B200 GPU. That figure, and the reported average benchmark score of 71.8, come from Sarvam's own announcement and should be treated as vendor claims until independently verified. The practical check is your own labelled test set.
Can Prism run on a business's own servers?
Yes, in principle. Its weights are released under the Apache 2.0 licence on Hugging Face, subject to a single GPU with at least 120 GB of memory in FP8 precision, per Sarvam's announcement coverage. It is also available through Sarvam's API. See the Analytics India Magazine report on Prism.
Should Prism replace our general language model?
No. Use Prism for fast, closed-choice decisions such as routing, classification, scoring and triage, and keep a general model for drafting, reasoning and open-ended cases. The strongest setup uses both: the decision model triages, and the general model handles only cases needing its language and reasoning ability.